Current setup is C-8 Pro parent, C-7 child connected on same network. C-7 is managing devices that are out of reach to the C-8, but only a handful, and all Z-wave, no Zigbee.
For the second time in as many weeks, I have run across this. The first time I accidentally restarted before I was able to do any troubleshooting, but this time I managed to catch this.
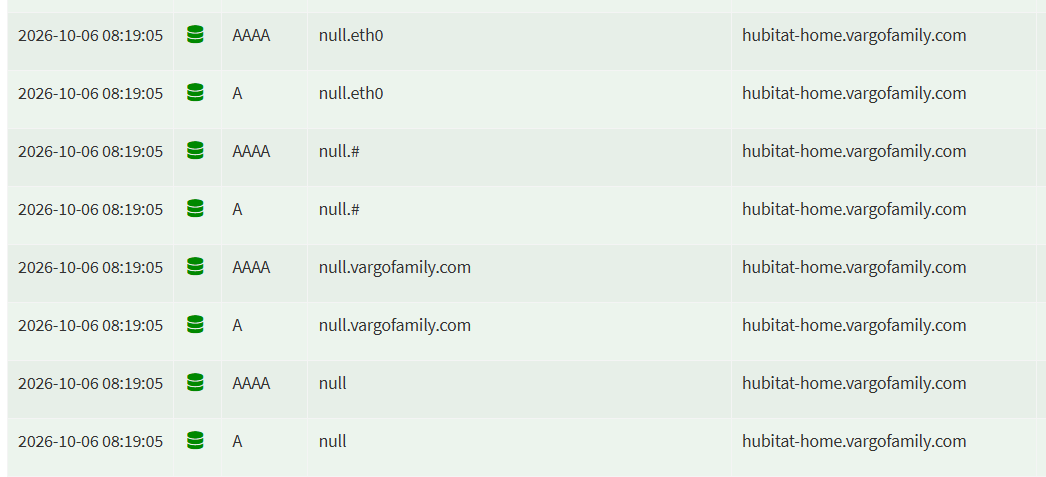
Backstory: Wednesday evening I received a series of automated alerts from my Proxmox cluster, specifically Nginx Proxy Manager and my redundant DNS for resource usage. These are all lightweight LXCs that dont really consume resources so immediately I knew something was up. Looking at the logs in NPE, I came across the following:
Time
Type
2026-09-30 19:22:41
AAAA
2026-09-30 19:22:41
A
2026-09-30 19:22:41
AAAA
2026-09-30 19:22:41
A
2026-09-30 19:22:41
AAAA
2026-09-30 19:22:41
A
2026-09-30 19:22:41
AAAA
2026-09-30 19:22:41
A
2026-09-30 19:22:41
AAAA
2026-09-30 19:22:41
A
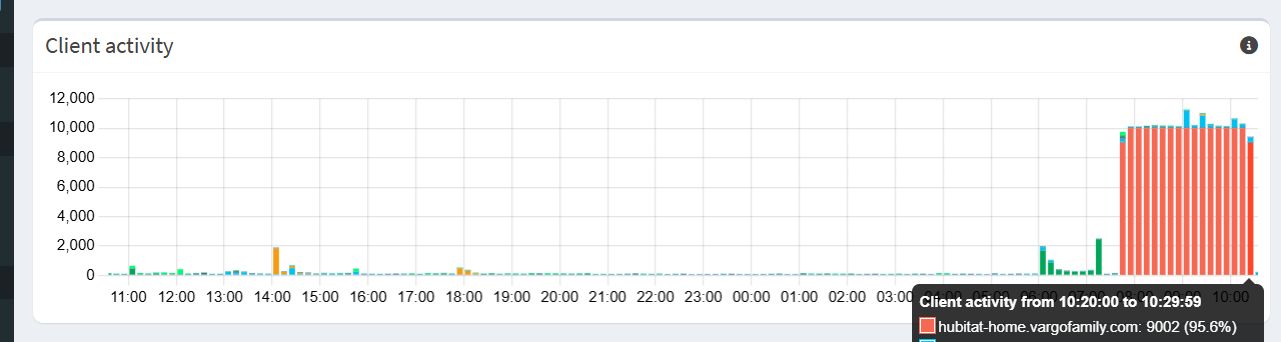
A quick count found approx 50k requests being made over a 5 minute period, all coming from the C-7 hub. The pattern of null, null.eth0, null.# and null.domain.com repeats over and over.
Is this a known issue? Whatever caused this, the hub was inaccessible via the URL I have for it in NPE as well as via IP. I had to hard cycle the hub at which point it stopped.
I have seen this before when I updated my switch firmware while the Hubitat was still connected. There have been other times also when the hubitat lost connectivity to a LXC which hosts my weather MQTT server while I was doing maintenance to the MQTT server.
I now watch out for that race condition and the only way I have found to correct is reboot the Hubitat.
Woke up this morning again to more alerts and the slave hub has again started hammering the network with bogus DNS requests. I have checked, none of my network appliances, switches etc updated overnight so it has to have started on its own. Can we create an issue so this gets tracked/resolved?